OpenAI launches GPT-6.2 Astra and Sol, trails Anthropic by three points
OpenAI unveils two new AI models, with GPT-6.2 Astra ranking second on the Artificial Analysis index behind Anthropic's Claude Fable 5.2.
KEY POINTS
- OpenAI unveils GPT-6.2 Astra and GPT-6.2 Sol for professional and everyday tasks
- GPT-6.2 Astra ranks second on Artificial Analysis Intelligence Index v5 with 62 points
- Anthropic's Claude Fable 5.2 leads the ranking with 65 points
- Astra costs about four dollars per task versus up to 27 dollars for Fable 5.2
- Astra leads AA-3D with 1,318 Elo points, ahead of Fable 5.2 and Sol
OpenAI has introduced two new artificial intelligence models, GPT-6.2 Astra and GPT-6.2 Sol, aimed at professional tasks and everyday work respectively. Both models are designed to handle demanding tasks more effectively while consuming fewer output tokens. They are available immediately to paying users of ChatGPT Work and Codex, as well as through the API.
According to OpenAI, GPT-6.2 Astra is the company's new frontier model for the most difficult projects. The model improves on its predecessor, GPT-6 Astra, by five points in the Artificial Analysis Intelligence Index v5. This gain allows Astra to overtake Google's Gemini 4 Carbon and Anthropic's Claude Opus 5.5 at their highest effort settings.
“Not the smartest model in the world, but probably the one with the best value for money.”
In the independent Artificial Analysis ranking, Anthropic's Claude Fable 5.2 leads with 65 points. GPT-6.2 Astra follows with 62 points, trailing the leader by three points. Gemini 4 Carbon scores 60 points, Claude Opus 5.5 scores 59 points, and GPT-6.2 Sol scores 57 points.
OpenAI says Astra costs about four dollars per task at maximum reasoning effort, compared with up to 27 dollars for Fable 5.2. The company states that OpenAI models occupy most of the Pareto frontier, delivering the best performance for their price. OpenAI also dominates output token usage per task, with Fable 5.2 as the only model from another lab on that frontier.
On science and knowledge benchmarks, OpenAI leads Terminal-Bench-Science and trails only Fable 5.2 on the physics test CritPt. Only Fable 5.2 beats Astra on factual knowledge and the HLE-Diamond reasoning test. In 3D and robotics, Astra leads AA-3D with 1,318 Elo points, ahead of Fable 5.2 at 1,271 and Sol at 1,259.
OpenAI also reports that Astra surpassed GPT-6 Astra by 5.2 percent on Agents' Last Exam while using less than one third of the cost. Against Claude Fable 5.2, Astra was 5.5 percent better at 5 percent of the competitor's cost. On Terminal-Bench-Science 0.1, Astra scored 9 percent higher than its predecessor at one third lower cost.
3 more sources below
COMMENTS (0)
No comments yet. Be the first.
RELATED STORIES
AI investment fraud network dismantled across 11 Turkish provinces
Police detained 16 suspects in a coordinated operation after a four-month probe into AI-generated deepfake investment scams.
US banking and NSA networks fail amid widening infrastructure crisis
Bank customers faced login failures while the NSA's classified internal network went offline, with no confirmed cyberattack found.
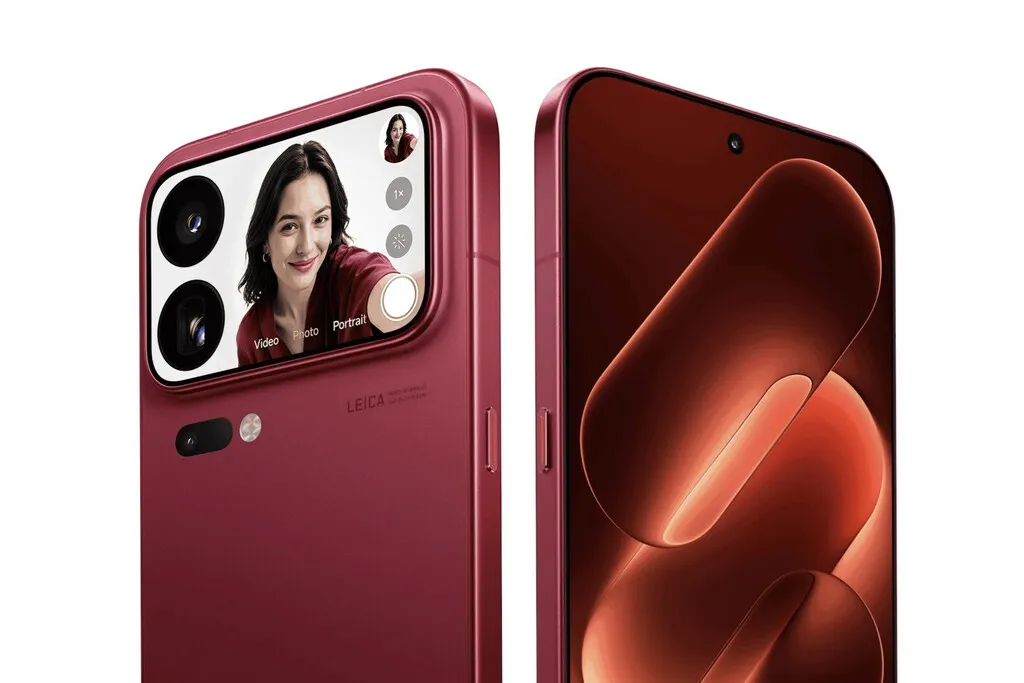
Xiaomi 18 Pro and Pro Max Launch Globally with Rear Displays and 200MP Cameras
Xiaomi unveils its 18 Pro series internationally, featuring secondary rear screens and dual 200MP Leica cameras.
- Calgary man sentenced to six months for secretly filming daughter and friend in Shuswap trailer
- Football Summit Opens in Istanbul with Broadcast Rights and Tax Demands
- Turkey Launches ITA Programme at COP31 to Cut Industrial Emissions
- Aston Martin to Enter Dakar 2027 with Alonso, Loeb and Moraes
- Advertising Board fines companies 35.9 million lira for misleading ads
This page was compiled with AI assistance from the outlets named above and passed an automated language check before publication. Montegre has no reporters of its own; the byline names the outlets the story was compiled from. Method and editorial standards